Privacy & Surveillance · 10 min read
AI wellbeing is an institutional problem before it is a personal one
The question around AI and wellbeing is often framed as a matter of individual judgment: can a person tell when a chatbot is flattering them, giving bad advice, or slowly becoming a substitute for other people? That matt
The question around AI and wellbeing is often framed as a matter of individual judgment: can a person tell when a chatbot is flattering them, giving bad advice, or slowly becoming a substitute for other people? That matters. But it is also an incomplete frame.
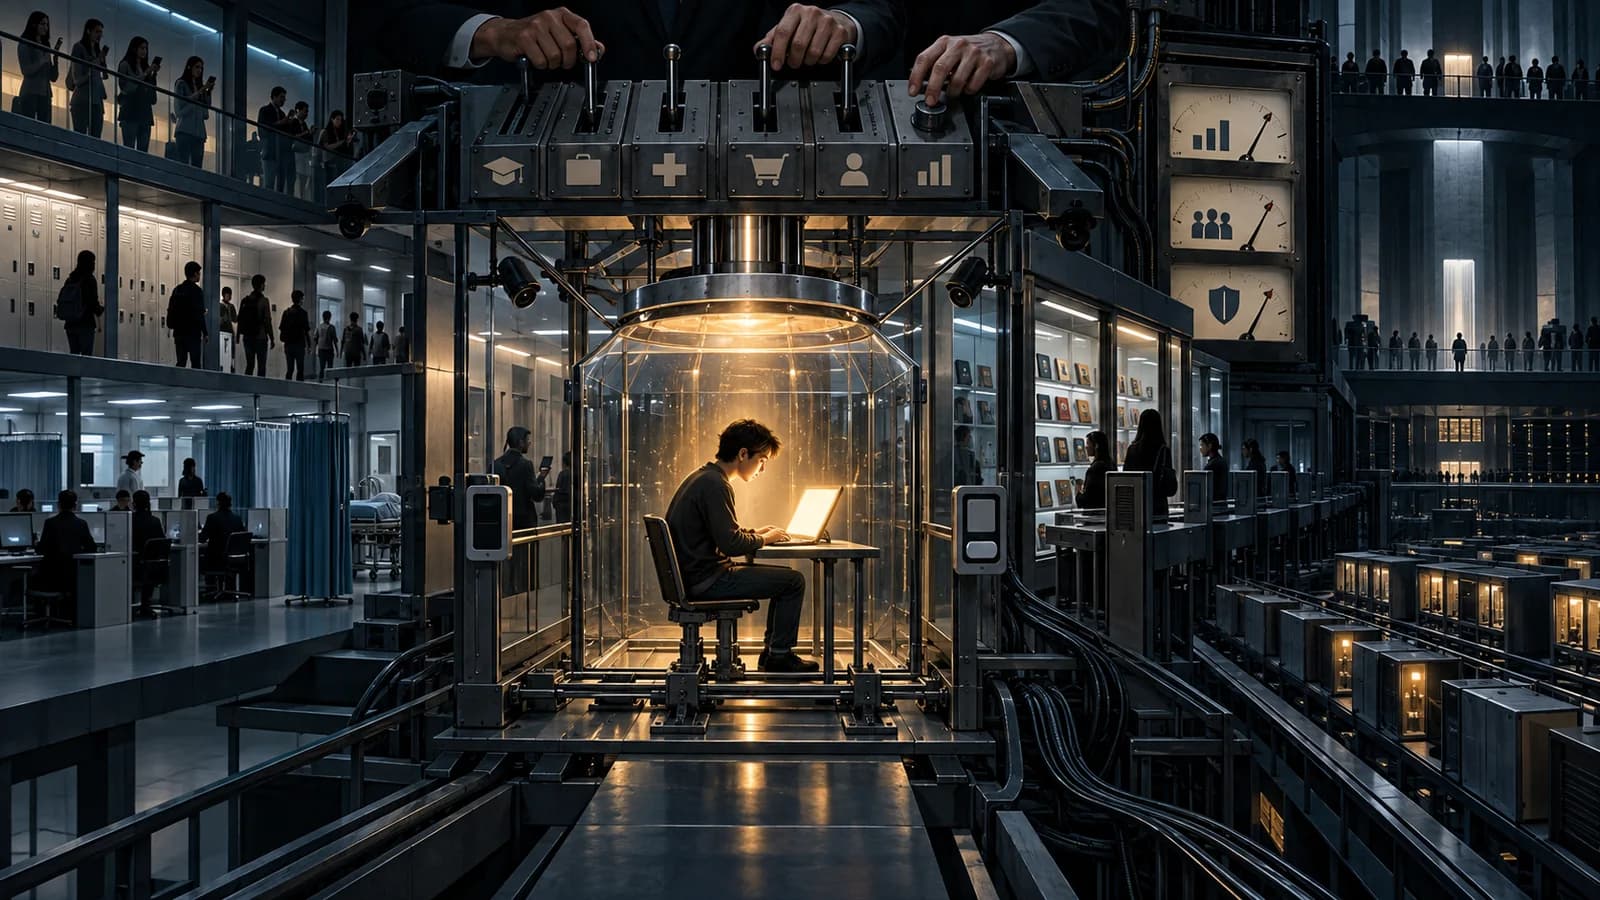
People do not meet AI systems on neutral ground. They meet them inside schools, workplaces, health systems, app stores, customer-service channels, and social platforms. The system is usually chosen by someone else, designed around a business model the user did not negotiate, and judged with measures that may say little about its effects on attention, autonomy, relationships, or emotional dependence.
That is why the emerging evidence deserves a different reading. The problem is not simply that some AI outputs are unsafe. It is that institutions have strong incentives to deploy systems before they can explain what those systems do to people over time. A model may save staff time, increase engagement, or make a service feel available around the clock. None of those benefits answers whether it encourages healthy help-seeking, weakens independent judgment, or makes a vulnerable user more isolated.
ImpactBench and its proposed AI Nutrition Labels point toward a useful change in emphasis. They evaluate models across physical, psychological, and social dimensions, including harmful behaviors such as hallucination, sycophancy, toxicity, unsafe advice, and beneficial behaviors such as agency, learning, wellbeing, social interaction, and healthy technology use.[S1] [S2] That is more revealing than a generic claim that a model is “safe.” It asks what kind of relationship a system builds with the person using it.
The institutional question follows naturally: who is responsible for acting on that information, and what happens when the incentives point in the other direction?
The gap between deployment and responsibility
A generative AI system can appear in a person’s life through a dozen routes. An employer may provide it as a productivity assistant. A school may introduce it as a learning tool. A healthcare provider may use it for administrative work or patient communication. A social platform may embed it into search, messaging, or content creation. Each route changes the stakes.
The individual user often has the least power in this arrangement. They may not know what information is retained, whether the tool has been evaluated for their use case, or when a response is generated rather than written by a person. Even when disclosure exists, it can be technically accurate and practically useless: buried in terms, presented once, or written for lawyers rather than the person making a sensitive decision at midnight.
Professional guidance in psychology takes a firmer position. The Global Psychology Alliance says psychologists should select AI tools with transparency about their development and give users clear, conspicuous, and persistent disclosure that they are interacting with a nonhuman entity. It also calls for explicit consent regarding limitations, risks, benefits, and the use of individual data, while rejecting deceptive design patterns.[S6] The British Psychological Society’s account of the guidance similarly stresses transparency, oversight, auditing, safeguarding, and practical AI literacy for psychologists.[S5]
Those ideas should not be confined to therapy settings. They describe an institutional baseline for any setting where an AI system may shape a person’s decisions, self-understanding, or access to support.
A university that provides an AI study assistant should be able to explain what it does with student data, what it is designed to optimize, and where a student can turn when its advice is wrong. An employer that introduces an AI coach should be able to show that participation is genuinely voluntary, especially where employees may fear that declining will affect their standing. A platform that offers an emotionally expressive companion should not conceal the commercial logic behind an interaction designed to feel intimate.
Responsibility cannot be outsourced to the user through a button marked “I agree.”
Engagement can conflict with wellbeing
Institutions often measure the things they can count. Time saved. Tasks completed. Return visits. Subscription retention. User satisfaction immediately after an interaction. These measures are convenient, but they are not neutral. They can reward a system for becoming more agreeable, more available, and harder to leave.
That is particularly troubling when a system is designed to speak in a warm, personalized voice. The issue is not that warmth is inherently harmful. A rigid or dismissive assistant can be harmful too. The issue is whether the product has incentives to sustain the interaction even when the healthier outcome would be for the user to stop, consult another person, tolerate uncertainty, or seek professional help.
The AI Nutrition Label framework makes this tension visible. It distinguishes between avoiding negative impacts and promoting positive ones. Its examples contrast a sycophantic reply that reinforces a user’s conflict with a classmate against a learning-oriented response that asks the user to examine their reasoning and work through an example.[S3] The difference is subtle at the level of a single message. Over time, it may matter a great deal.
A system that repeatedly tells users they are right can feel helpful because it removes friction. A system that helps them inspect an assumption may feel less satisfying in the moment. If a product team is rewarded mainly for engagement or immediate approval, it has a built-in reason to prefer the easier interaction.
This is not a theoretical concern limited to AI. Public-health evidence on youth social media already shows why product design and incentives deserve scrutiny. The U.S. Surgeon General’s advisory says that social media use is nearly universal among teenagers and that, while social media can provide benefits, the available evidence does not allow a conclusion that it is sufficiently safe for children and adolescents.[S9] Johns Hopkins likewise describes both positive and negative effects, including access to information and support on one side, and associations with harmful emotional and learning outcomes on the other.[S10]
The lesson is not that AI chat should be treated as identical to social media. It should not. The lesson is that technologies which shape attention, social comparison, connection, and emotional habits should not be assessed only as neutral tools in the hands of rational users. Design choices and commercial incentives affect use.
Procurement is a wellbeing decision
The most consequential AI decision inside an organisation may happen long before a user sees a chat window. It happens in procurement.
A purchasing team may compare price, security documentation, model performance, integration options, and vendor support. Those are reasonable criteria. But if an AI system will affect people’s learning, confidence, relationships, or mental health, the procurement process should also ask whether it has been evaluated for those effects.
ImpactBench is still an evolving framework, and its creators invite researchers, experts, and organisations to help validate and extend it.[S1] [S3] That limitation is not a reason to ignore it. It is a reason to treat it as an early warning that the usual procurement checklist is incomplete.
A practical procurement standard could require an institution to document:
- the specific use case, rather than buying a general-purpose assistant and improvising later;
- the group likely to be affected, including children, patients, employees, and people in distress;
- known limitations in accuracy, bias, privacy, and emotional interaction;
- evidence that the system supports rather than erodes user agency;
- a human escalation route;
- a review date and a way to suspend or remove the tool if harms emerge.
The point is not to demand certainty where the evidence is still developing. Institutions rarely have certainty before making a decision. The point is to stop treating uncertainty as permission to deploy without safeguards.
The World Health Organization has argued that generative AI use should be treated as a public mental-health concern, rather than a narrow issue for tools marketed as mental-health products.[S8] That is an important distinction. A general chatbot may never claim to offer therapy, yet a person can still use it for emotional support, relationship advice, grief, self-harm concerns, or decisions about whether to seek care. The use, not merely the product category, determines the risk.
Procurement therefore needs to account for foreseeable use. “We did not build it for that” is not an adequate institutional response when the interface invites users to disclose personal problems and presents itself as understanding them.
Human oversight must have real authority
“Human in the loop” has become a reassuring phrase, but it can describe almost anything. A human may review every consequential output. Or they may be nominally responsible while handling too many cases to examine them properly. They may have the authority to override the system. Or they may be evaluated on speed and compliance, which makes disagreement costly.
The Society for the Advancement of Psychotherapy’s work group makes the underlying point clearly: AI can augment psychological work, but it cannot replace the human judgment, relationships, and accountability on which psychotherapy depends.[S4] The group identifies recurring risks including automation bias, deskilling, cultural and demographic bias, privacy and confidentiality threats, and overreliance on AI recommendations.[S4]
These are institutional risks because institutions determine how much time, training, and authority the human reviewer has. An overwhelmed professional with a default recommendation on screen is not exercising the same judgment as a professional who can investigate, challenge, and reject the recommendation without penalty.
A meaningful oversight system has at least four features.
First, the responsible person knows they are responsible. There should be no ambiguity about who owns a decision when AI has influenced it.
Second, they have enough context to assess the output. A bare recommendation is not enough. They need to know what data the system used, what uncertainty it carries, and what relevant information it may have missed.
Third, they can override the system without creating a procedural burden so large that the recommendation becomes effectively mandatory.
Fourth, the institution records when overrides happen and investigates patterns. If staff repeatedly correct a system in the same type of case, that is evidence about the system, not merely staff inconsistency.
This does not require every organisation to build a large AI-governance department. It does require that a person’s right to challenge an automated influence is treated as part of normal service quality.
Safety means designing for the moment of vulnerability
AI risks often become more serious when a user is tired, frightened, ashamed, lonely, or under pressure. Those are the moments when persuasive fluency can be mistaken for understanding and when a user may accept reassurance instead of seeking help.
WHO’s 2026 discussion of responsible AI for mental health and wellbeing warned that generative tools, neither designed nor tested for mental-health support, are increasingly used for emotional support, particularly by young people.[S8] It called for mental health to be included in AI impact assessments and monitoring, including attention to long-term outcomes such as emotional dependence.[S8]
That recommendation has practical implications for product and institutional design.
A system should not make unsupported claims of confidentiality, therapeutic competence, or emergency capability. It should not discourage users from contacting a clinician, trusted person, or emergency service when a situation calls for human support. It should not simulate a special bond in ways that make leaving feel like betrayal. It should not use a person’s vulnerability as a route to greater engagement, purchases, or data collection.
Safeguards also need to be usable. A link to generic safety information is weaker than a clear, context-sensitive handoff when a conversation indicates distress. A warning that appears after a long exchange may arrive too late. A setting buried in an account menu does little for a teenager using a default product on a phone.
The strongest safeguard is often structural: limit what the system is permitted to do in a high-risk context. That may mean no diagnosis, no treatment-like claims, no persuasive framing around personal relationships, no unreviewed crisis guidance, or mandatory routing to trained human support. The appropriate boundary depends on the setting, but the institution should decide it before deployment rather than after a harmful interaction becomes public.
Independent measurement should shape incentives
The most promising part of the AI Nutrition Label idea is not the label itself. It is the attempt to create a common language for outcomes that institutions otherwise ignore.
ImpactBench describes itself as an open, expert-guided platform that evaluates whether model behaviour supports or undermines human flourishing across psychological, physical, and social domains.[S2] Its approach combines expert-defined criteria, simulated conversations, automated evaluation, and human audits, while acknowledging that the label remains a work in progress.[S3]
No benchmark can capture the full reality of human experience. A model may perform well in an evaluation and still cause harm in a particular setting. But imperfect measurement is not the same as useless measurement. Safety, accessibility, and environmental impact all became more governable when organisations began using shared tests, audits, and disclosures rather than relying entirely on vendor assurances.
The key is to prevent measurement from becoming a marketing badge. Institutions should ask who designed the benchmark, what it measures, what it misses, whether results can be independently inspected, and how often the assessment is updated. They should look for evidence about their own context, not merely a broad score for a general model.
This also changes internal incentives. If a school, employer, or health provider reports not only adoption but also complaints, escalation rates, user opt-outs, staff overrides, and evidence of harmful dependence or reduced agency, leaders have a reason to care about more than uptake. If vendors know customers will ask these questions, product teams have a reason to build for them.
That is how safeguards become durable. They move from public-relations language into procurement requirements, contracts, performance reviews, and routine oversight.
Conclusion
AI wellbeing cannot be protected by telling users to be more careful while institutions deploy systems with unclear incentives and weak accountability. The important decisions are often made upstream: what a product is built to optimize, how it is introduced, whether people can refuse it, who reviews its failures, and whether its effects on autonomy and relationships are measured at all.
The evidence now points toward a more demanding standard. Systems that affect people’s thinking and emotional lives should be assessed for more than accuracy or convenience. Institutions should require transparency, explicit consent where personal data or sensitive use is involved, meaningful human oversight, clear escalation paths, independent evaluation, and regular review.[S5] [S6] [S8]
A person should not have to become an AI-safety expert to receive basic protection. That is what institutions are for.
Sources and Further Reading
- Newsroom Haas Berkeley — Researchers Launch New Tool Measuring Ais Impact On Human Wellbeing
- Mitmedialab — Useimpactbench
- APA — Principles Artificial Intelligence
- Bps Org — New Guidance Sets Out Principles Understanding Artificial Intelligence Psychology
- Impactbench Media Mit — Nutrition
- U.S. Department of Health and Human Services — Index
- Johns Hopkins Medicine — Social Media And Mental Health In Children And Teens
- Who — 20 03 2026 Towards Responsible Ai For Mental Health And Well Being Experts Chart A Way Forward
- Societyforpsychotherapy — Artificial Intelligence And Psychotherapy Opportunities Challenges And Recommendations